ANACOMAI VISION · BUILT TO FIND
Tell Vision what you're looking for.
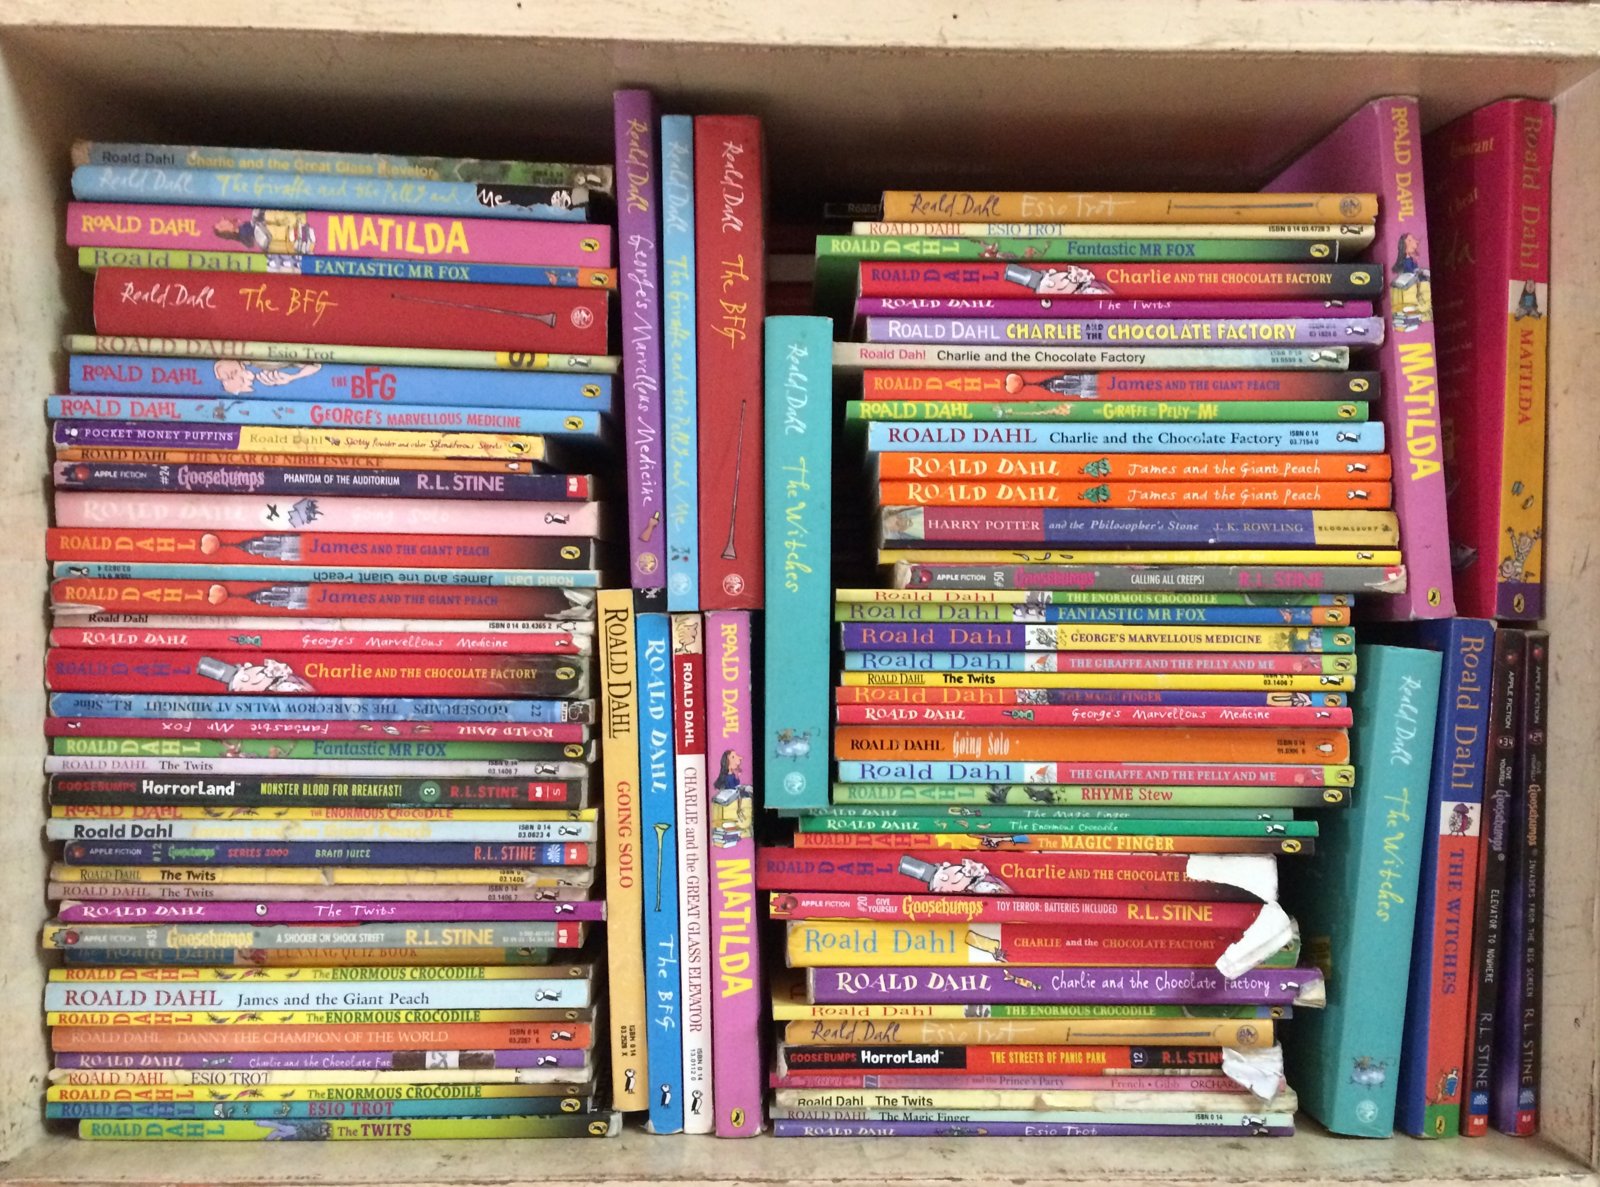
AnacomAI's own fine-tuned vision model turns a plain-English request into a place on your photo. Find an object, a book, or a label and see it outlined in context.
What you can use it for
- Books and labels
- It reads titles and labels, even on spines turned sideways.
- Everyday things
- Describe it in your own words: the red screwdriver, the charger next to the laptop.
- Your own stuff
- Save a photo of your backpack once, then ask for “my backpack”.
- Things you've lost
- Keep photos in Memory and ask where you last saw something.
- Live
- Point your phone camera around a room while it looks for you.
MEET VISION
Made to point, not just describe.
Vision is AnacomAI's fine-tuned image model for phrase-based object locating. Ask for “the red screwdriver” or a book title; it returns coordinates that the app draws over your original photo.
Your words in
Describe the thing naturally. Vision searches by phrase, colour, or visible title.
A place out
Get a box on the photo, with the surrounding scene still visible.
AnacomAI owned
Our fine-tuned weights are built on Florence-2; uncertain matches can fall back to AnacomAI's wider vision pipeline.
Vision is a specialist locator, not a general chat model. Results vary with the image and request. Its current benchmarks are small and do not establish that it is more accurate than larger models.